Preview
Interface at a glance
Screenshots taken from ThinkData's production UI with real data
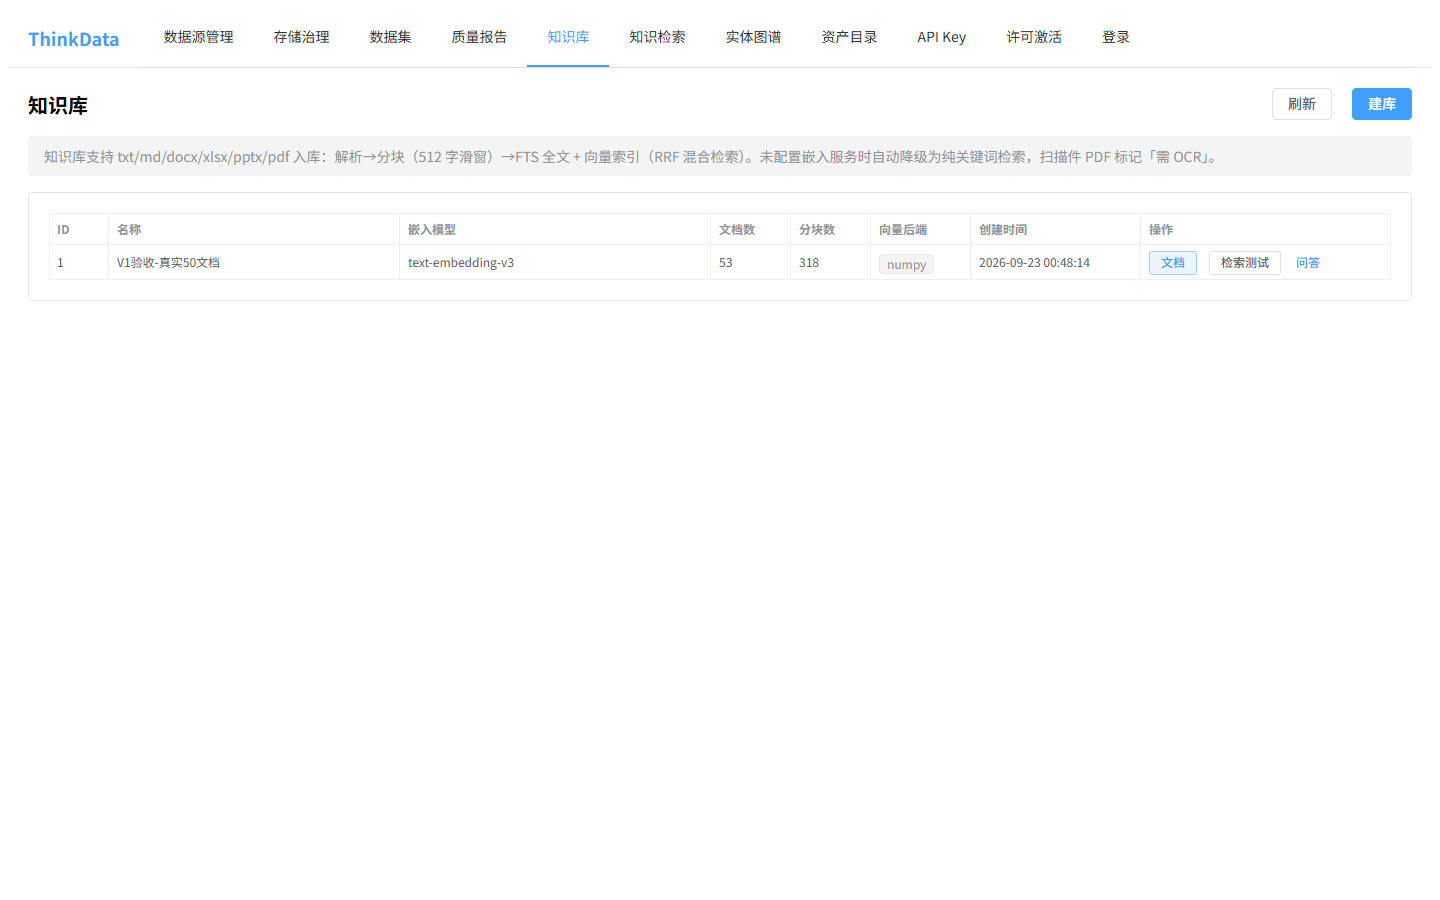
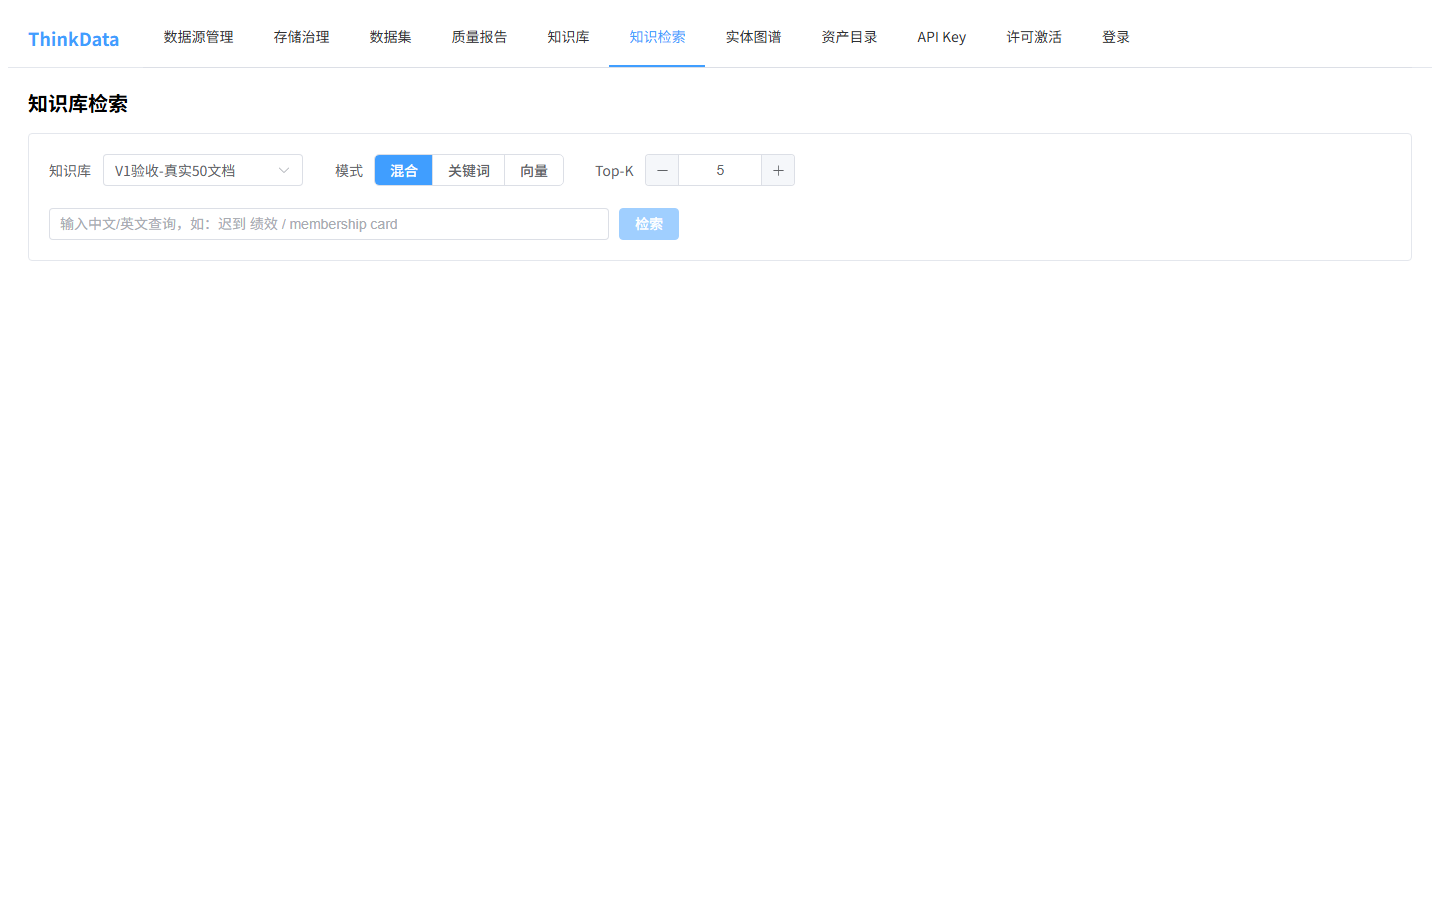
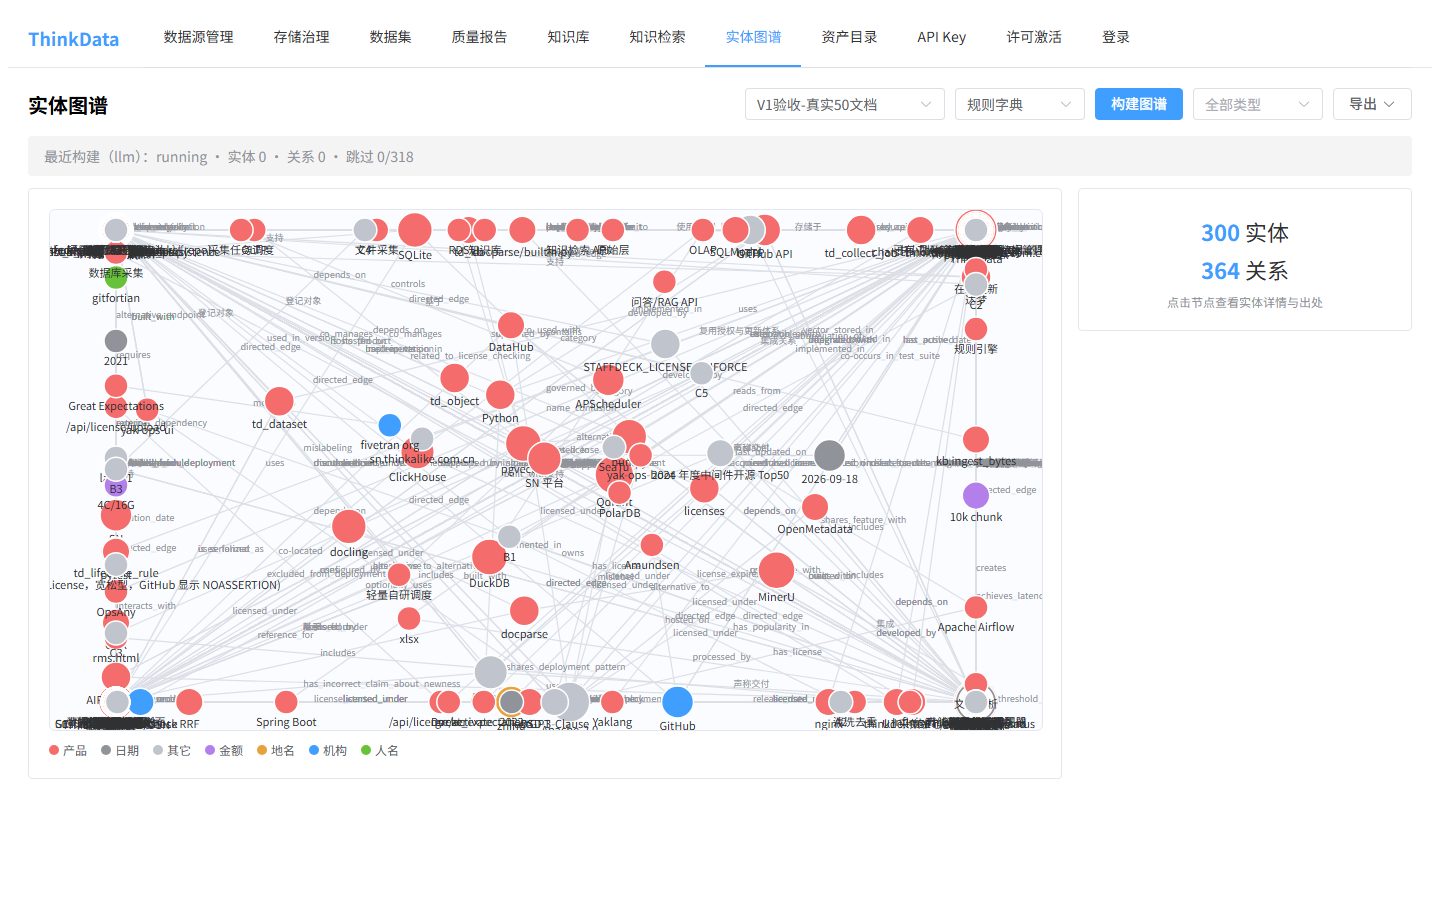
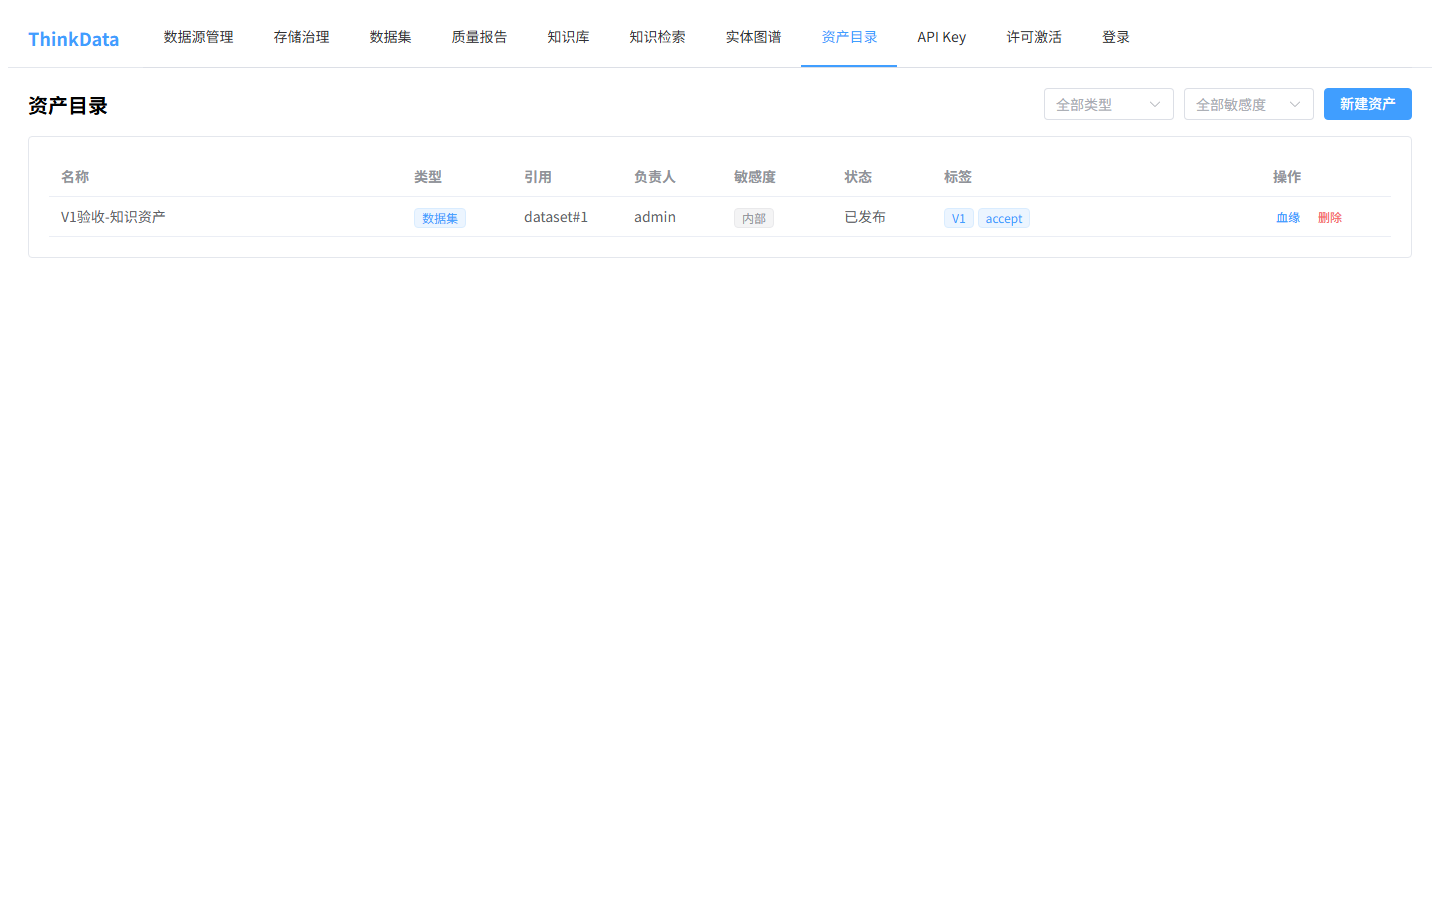
Unify and govern data scattered across systems, curate it with quality checks, build a searchable and answerable knowledge base, mine it deeply with entity recognition and knowledge graphs, and register it as reusable, grantable knowledge assets. FastAPI + SQLModel + SQLite core, DuckDB curation to Parquet, Vue3 + Element Plus UI.
Collect, govern, curate, build KB, graph, assetize, serve and license — data keeps gaining value as it flows
Local-directory, URL-fetch and DB-snapshot collectors with scheduled dispatch and job mutex locks build a reliable data foundation.
Object-storage intranet archiving with sha256 dedup, lifecycle tiering and signed downloads; capacity and cost are visible, staging overflow degrades gracefully.
In-process DuckDB curation produces Parquet with encoding normalization, row dedup and type inference; a built-in quality rule engine grades results pass/warn/fail.
Parses docx/xlsx/pptx/pdf into a knowledge base with FTS5 Chinese full-text and vector hybrid retrieval (RRF fusion) and knowledge-base Q&A.
Dual-mode NER (rule dictionary + LLM) extracts entities and relations, exports JSON/CSV/Cypher, and renders a force-directed graph you can reason over.
Datasets, knowledge bases and services are cataloged together with auto-registered upstream/downstream lineage and cycle detection, under controlled sensitivity and permissions.
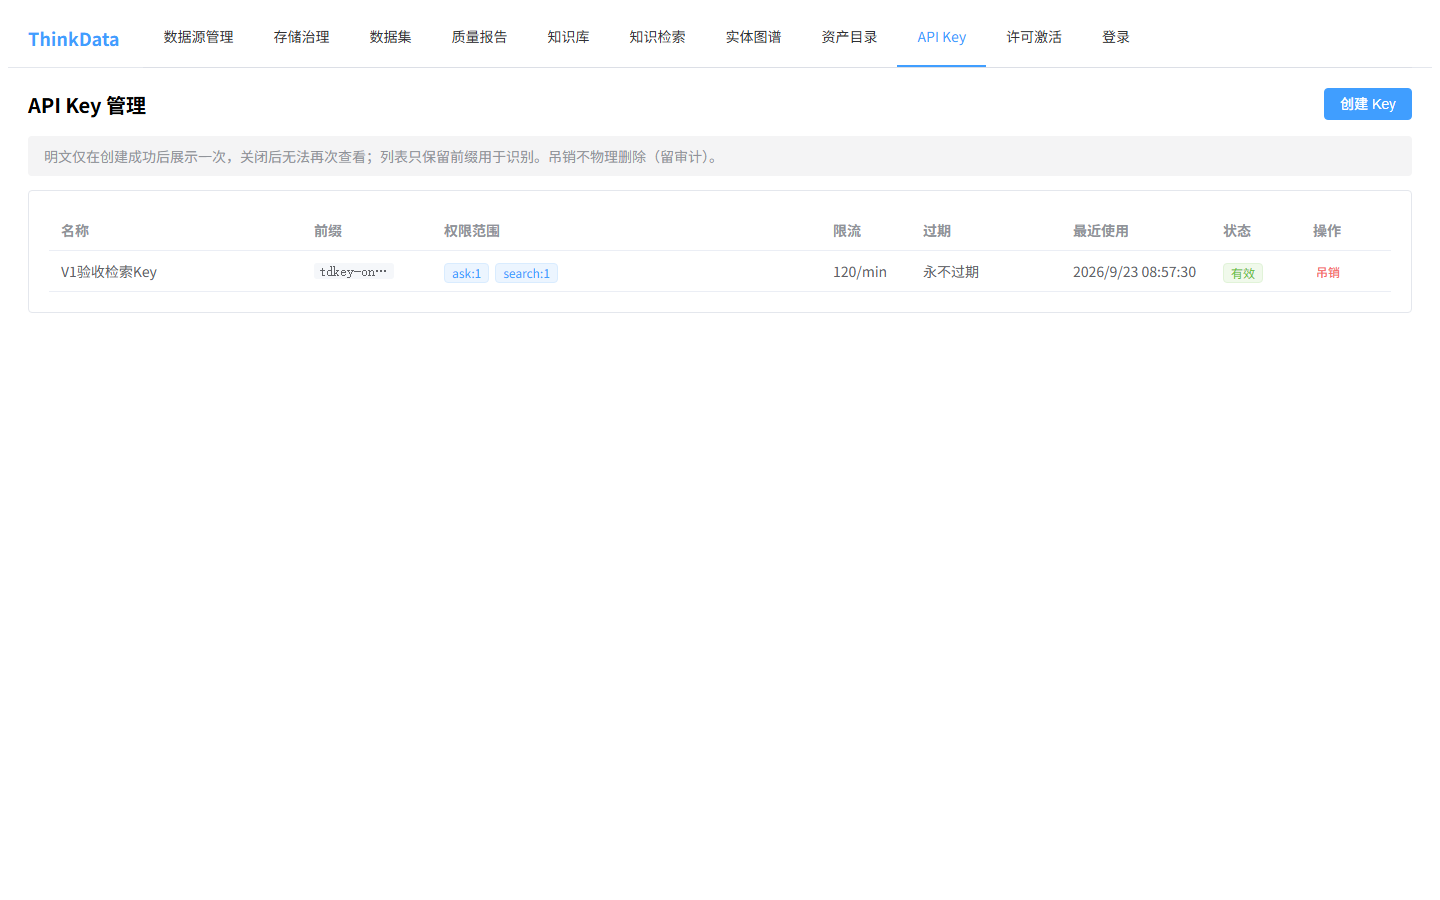
API keys (SHA256, scopes, rate limits, revocation) expose search, Q&A and dataset-snapshot endpoints for upstream AI apps and digital employees.
One-machine-one-code SN activation, a 90-day free trial and a read-only demo mode when unlicensed; one-click online update with automatic rollback on failure.
Built-in document parsing, hybrid retrieval, entity/relation extraction and graph pipelines mine unstructured documents and structured tables alike, forming a searchable, answerable, reasoning-capable knowledge asset.
Processed results are registered as data assets — searchable, grantable, reusable — and, via the open API, linked to the suite's knowledge bases and digital employees so data keeps appreciating in use.
Standardized, traceable, reusable
Local / URL / DB-snapshot ingestion with scheduled dispatch and mutex locks.
Object-storage intranet archiving, dedup and lifecycle tiering with cost visibility.
DuckDB curation to Parquet with quality checks; parse documents into a searchable, answerable KB.
NER and graphs mine deeply; register assets and open APIs — searchable, grantable, linked.
Use cases
Screenshots taken from ThinkData's production UI with real data
ThinkData offers an SN-licensed 90-day free trial and offline on-premises deployment — a single 4GB server is enough. Contact us to book a demo or get a deployment plan.
Book a demo / inquiryThinkData is a data & knowledge platform by ThinkAlike spanning multi-source collection, cloud storage governance, curation & quality, document knowledge base, entity recognition & knowledge graph, asset catalog & lineage, open API service and SN licensing & online update.
Yes. ThinkData uses SN licensing: after installation you can claim a 90-day free trial online and activate with a one-machine-one-code SN before it expires; unlicensed it runs in a read-only demo mode (readable, not writable) — no data loss.
One-click online update from the SN platform: the install script backs up code and database, runs a health check after replacement, and automatically rolls back to the previous version on failure.
Backend FastAPI + SQLModel with SQLite for metadata/runtime; DuckDB for curation producing Parquet; retrieval is FTS5 Chinese full-text + vector (numpy, optional pgvector backend) fused via RRF; front end Vue3 + Element Plus.
ThinkData processes data into reusable knowledge assets that, through the open API, link with ThinKM and the digital employees for retrieval.
Yes. ThinkData ships as an offline, on-premises intranet deployment; data never leaves your domain and a single 4GB server is enough. The hosted demo is coming online — for a demo or deployment plan contact contact@thinkalike.com.cn.